llama.cpp prompt lookup: a missing ampersand beat a faster hash map
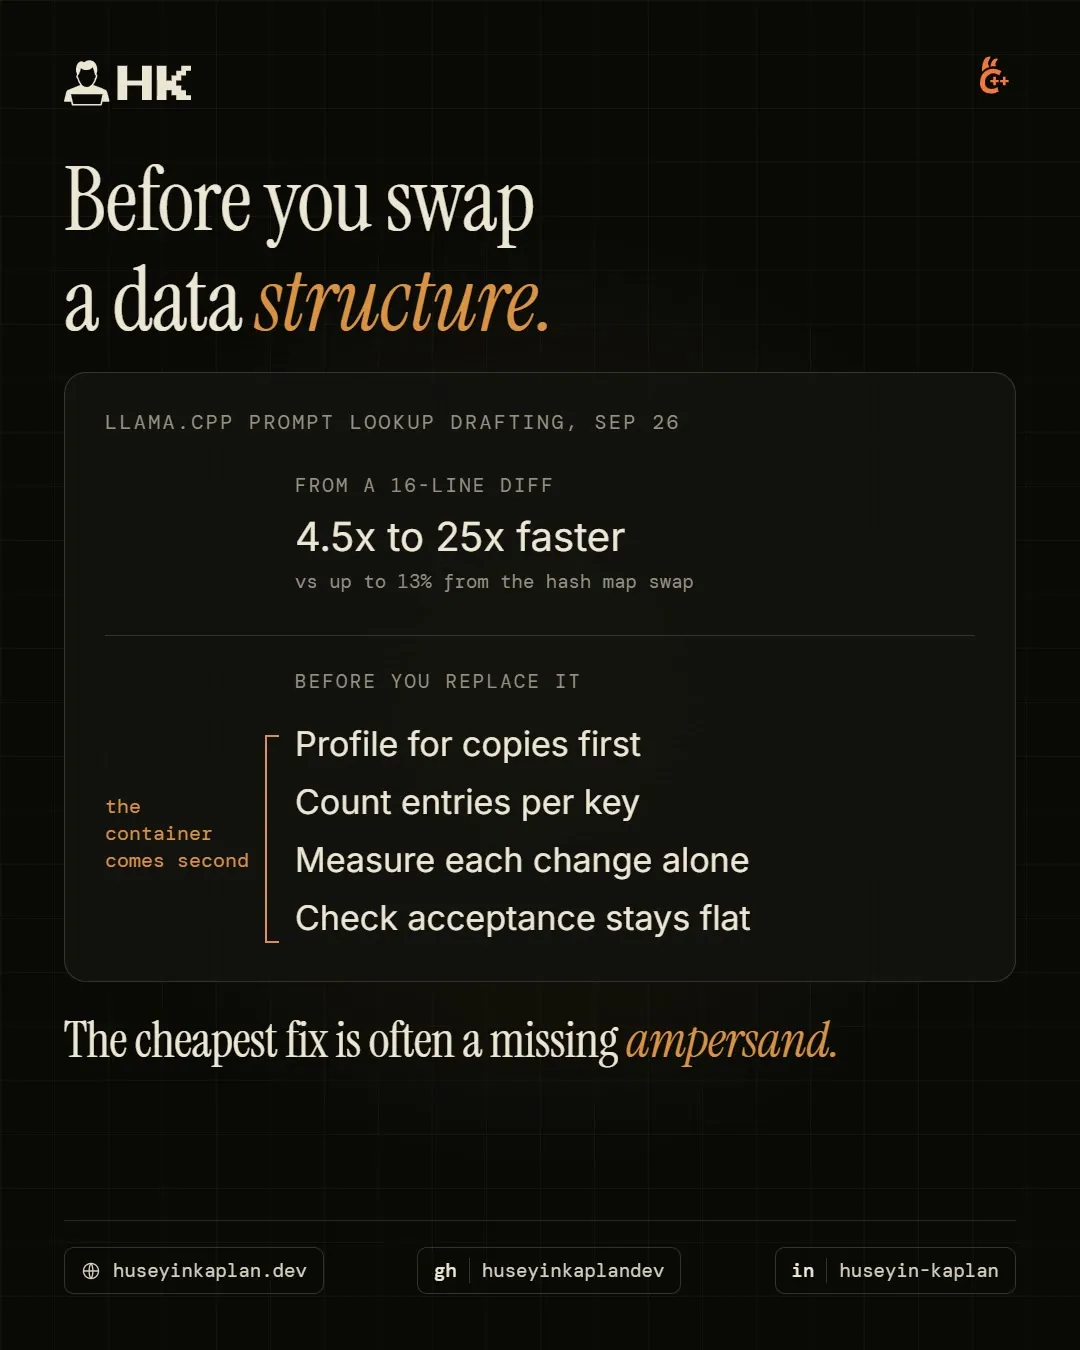
In llama.cpp prompt lookup drafting, reading maps by reference gave 4.5x to 25x, while a flat hash map added only up to 13%. Profile for copies first.
Swapping in a faster hash map is the classic C++ speedup. In llama.cpp's prompt lookup drafting, it barely moved the number.
Hayder Tirmazi published his tuning work on Saturday. Prompt lookup decoding drafts tokens from n-gram counts, so the draft model is nearly free. The code around it wasn't.
The biggest win was a 16-line diff: stop copying the inner maps on every draft step, read them by reference. Drafting got 4.5x to 25x faster.
The flat hash map that came next pulled in about 4,500 vendored lines for up to 13% faster drafting. His first sorted vector version ran slower than what it replaced, until he rewrote the binary search. Daniel Lemire's early threshold exit then took the total to 140x.
Before you replace a data structure:
- Profile for copies first.
- Count how many entries a key holds.
- Measure each change on its own.
The cheapest fix is often a missing ampersand.
Notes on this post
Join in
Leave a comment.
Sign in to add your note to this post.
Only your name and avatar are used.