Opus 5.5 and GPT-6 Sol/Luna: the price war moved to cached tokens
Opus 5.5 cut cache reads 60% and GPT-6 gives 90% off cached input, so agent costs now hinge on a stable prompt prefix.
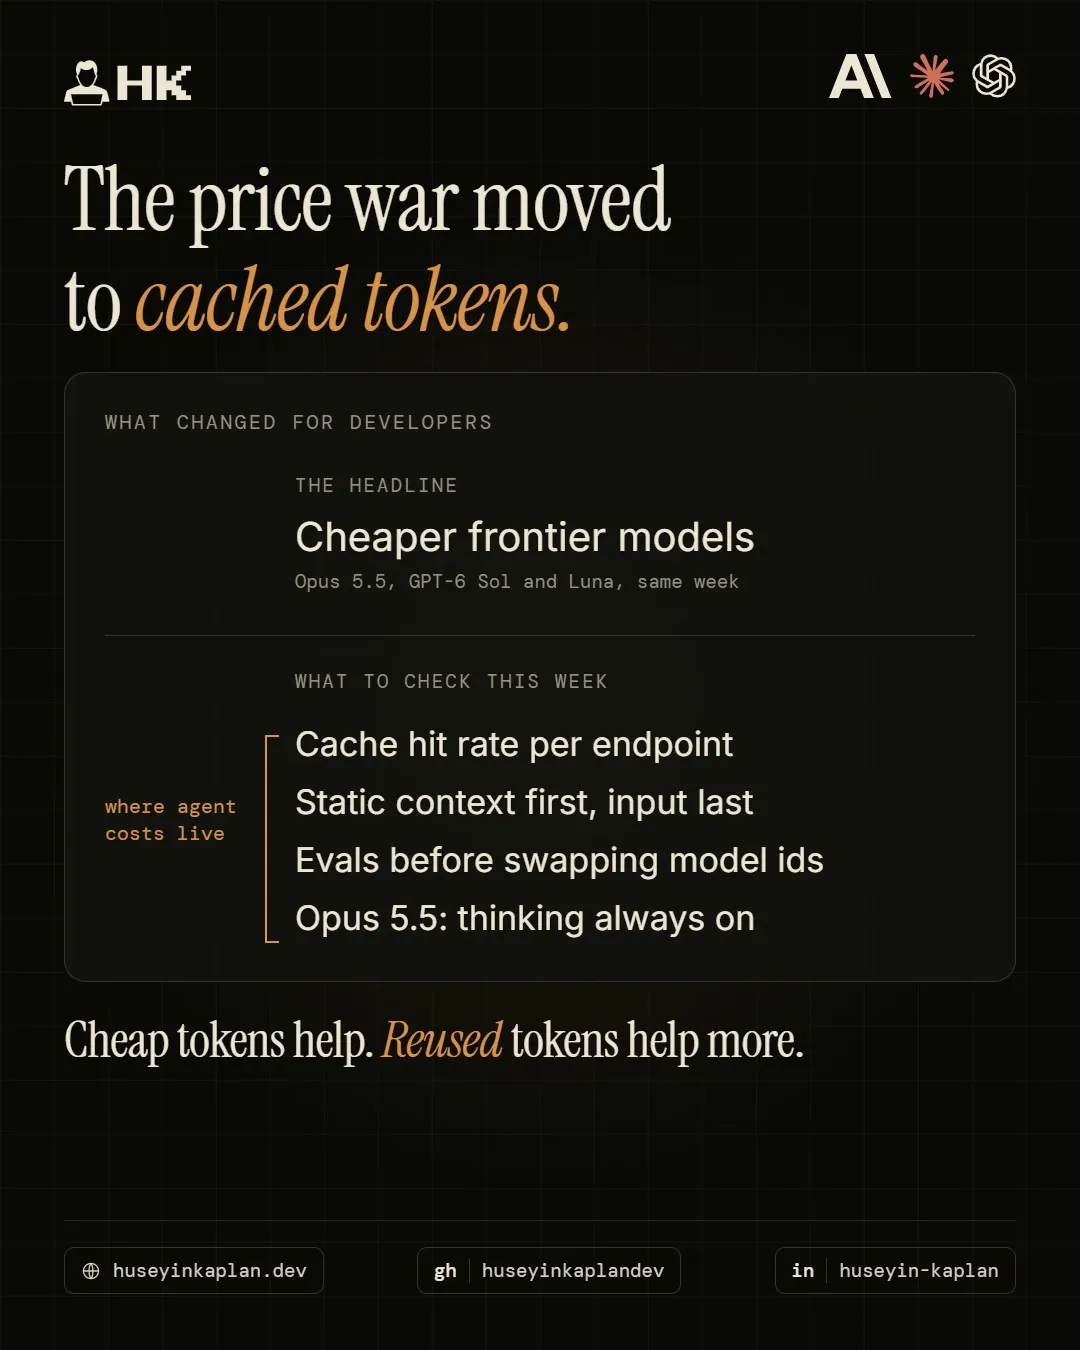
Two frontier model launches landed within a day of each other. The headline is cheaper tokens. The real story is cached tokens.
Anthropic shipped Claude Opus 5.5. Input and output got 20% cheaper, but cache reads dropped 60%. Anthropic says cache reads make up most of the cost of agentic and coding work.
OpenAI shipped GPT-6 Sol and Luna at half the previous API price. It also gives 90% off cached input reads, and changing reasoning effort or tools no longer breaks the cache.
So an agent's bill now depends less on which model you pick and more on how stable your prompt prefix is.
What to check this week:
- Cache hit rate, per endpoint
- Static context first, user input last
- Your eval set, before swapping model ids
- Opus 5.5 can't run with thinking off. Test your integration.
Cheap tokens help. Reused tokens help more.
Notes on this post
Join in
Leave a comment.
Sign in to add your note to this post.
Only your name and avatar are used.