Magnitude vs llama.cpp: 2x faster decode, only 9% faster prefill
Magnitude's 2x speedup is decode, but at 64K context an agent turn is mostly prefill, so the whole turn gets only about 12% faster.
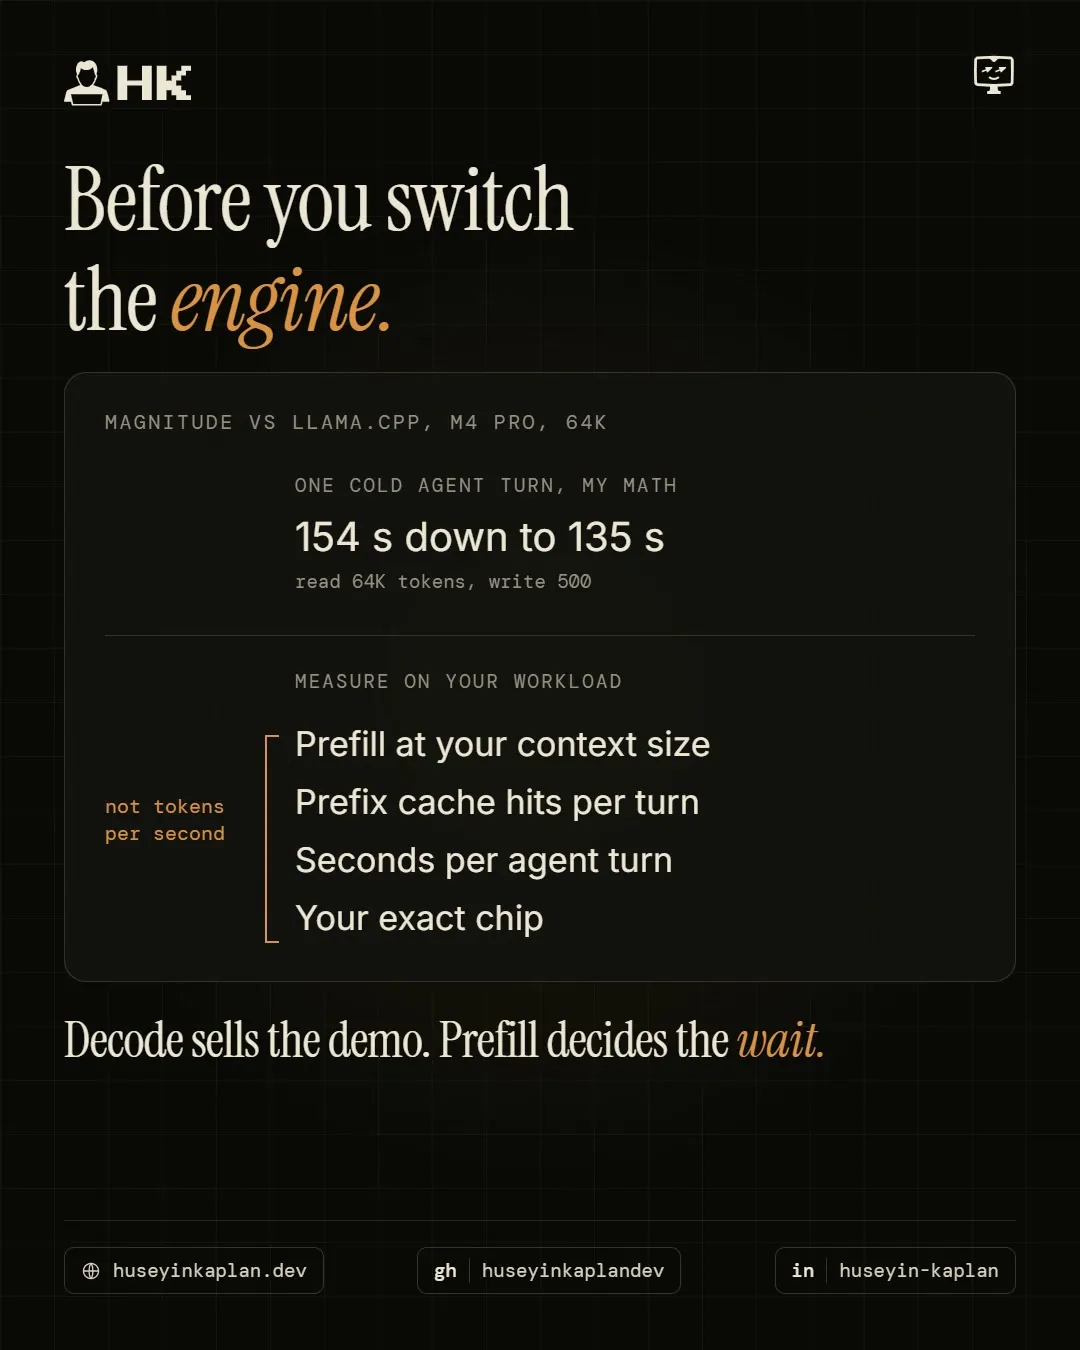
"Up to 2x faster than llama.cpp" was the headline on Magnitude's Launch HN this week. The 2x is decode. Prefill moved 9%.
Magnitude is an open source local inference engine for agents. It tunes its GPU kernels on your own machine, about a minute per model.
Their Mac numbers, Qwen 35B at 64K context:
- Decode went from 30 to 57 tokens per second.
- Prefill went from 466 to 507.
I ran the math for one cold agent turn. Reading 64K tokens takes over two minutes on both engines. Writing a 500 token answer drops from 17 seconds to 9. The turn takes about 12% less time, not half.
An agent turn is mostly reading: tool output, diffs, whole files. That's prefill.
Before you switch engines, measure:
- Prefill speed at your real context size
- Prefix cache hits between turns
- Seconds per agent turn, not tokens per second
- Results on your exact chip
Decode sells the demo. Prefill decides the wait.
Notes on this post
Join in
Leave a comment.
Sign in to add your note to this post.
Only your name and avatar are used.